Start with a question a child can answer and a language model can bluff: “How many red cubes are below the large red sphere?” The interesting part is not the answer. It is the machinery that makes the answer necessary.
00 / The hookA scene, a question, a program.
The image below is a CLEVR scene from the official dataset: simple objects, simple attributes, simple relations. The question is compositional. It contains a count, a filter, a shape, a colour, a size, and a spatial relation. A monolithic vision-language model can learn to answer questions like this from enough examples. But it cannot show you the steps, and it tends to fail when the steps are recombined in a way it has not seen.
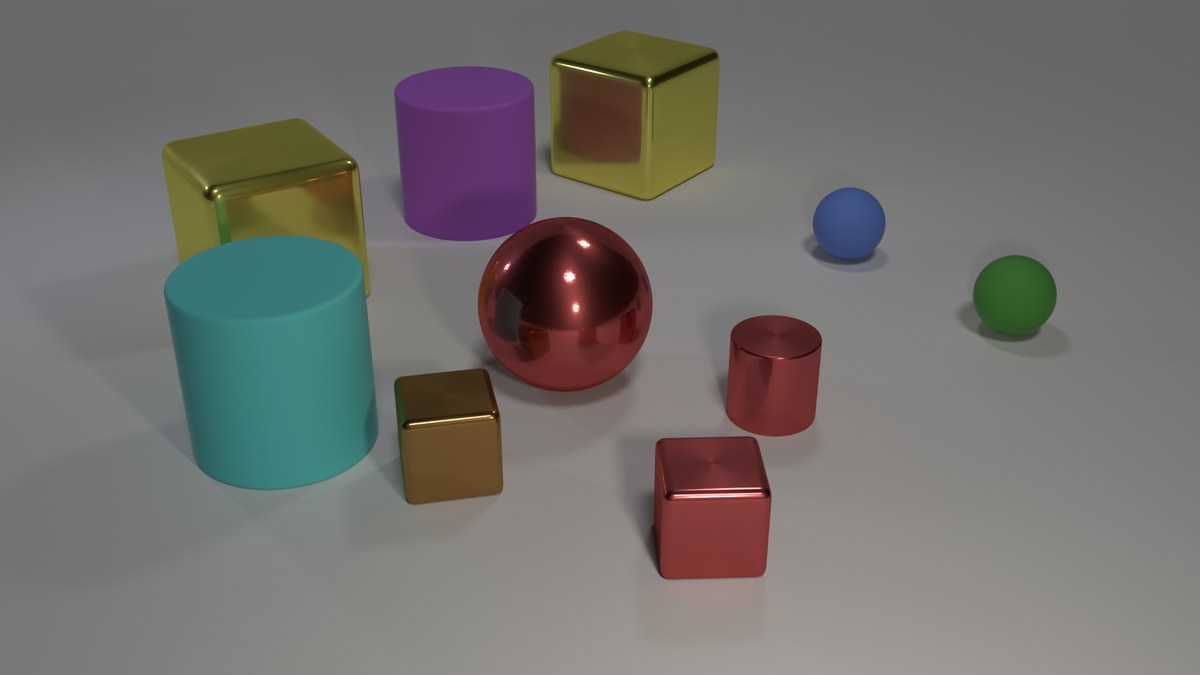
The Neuro-Symbolic Concept Learner (NS-CL) answers the question in four steps. First, a neural perception module turns the image into an object-centric scene representation: a set of objects, each with attributes such as colour, shape, size, and material, plus spatial relations. Second, a semantic parser turns the question into an executable symbolic program. Third, a symbolic executor runs the program over the scene representation. Fourth, the whole system is trained from question–answer pairs, without program annotations, using a curriculum over the compositional space.
count( filter( cube, filter( red, below( large_red_sphere ) ) ) )The answer is one: the red cube below the sphere. The program is not an explanation bolted on after the answer. It is the computation. The neural network supplies the meaning of red, cube, and below by grounding them in the scene representation. The symbolic program supplies the composition: it says how those meanings are combined. That division of labour is the smallest complete picture of neurosymbolic AI.
The question is not whether the model can answer. It is whether the answer is composed from parts that can be inspected, recombined, and checked.
CLEVR is synthetic, the concepts are closed, and the questions are generated from a grammar. NS-CL is a proof of concept about composition and grounding, not a deployed visual reasoner. The gap between this scene and a kitchen, a street, or a hospital is the rest of the course.
01 / The gapWhy pure paradigms fail — and why the failure is specific.
The usual story is that neural networks are good at perception and bad at reasoning, while symbolic systems are the reverse. The story is too simple, but it locates the problem. The failures are not generic; they cluster around the interface between representation and reasoning.
Pure neural systems
A neural network can learn a mapping from pixels, text, or proprioception to an answer or an action. It is robust to noise, scales with data, and improves with architecture and compute. What it does not reliably do is systematically compose what it has learned. Dziri et al. show that transformer performance on multi-step compositional tasks degrades with the depth of the reasoning chain and relies on patterns seen during training rather than a general procedure (arXiv:2305.18654). The failure is not that the model cannot learn the parts; it is that it does not reliably recompose them.
The same pattern appears in planning. Large language models can produce plausible plans, but they cannot guarantee that a plan is executable in a particular environment. Kambhampati et al. argue that LLMs should generate candidates, while external critics and verifiers check them — the LLM-Modulo framework (arXiv:2402.01817). In embodied settings, the Embodied Agent Interface separates planning errors from grounding errors and shows that LLM agents fail in characteristic ways: hallucinated preconditions, ignored effects, and incorrect grounding of objects and actions (arXiv:2410.07166).
These are different benchmarks, but they share a shape: the model is fluent, confident, and not accountable to a model of the task. It can produce the next token; it cannot show that the next token is forced.
Pure symbolic systems
A symbolic system has the opposite profile. Given a formal model — a set of predicates, axioms, preconditions, and effects — it can derive consequences, prove theorems, and plan. It is compositional by construction and verifiable by construction. What it cannot do is acquire the model from raw experience. The knowledge-acquisition bottleneck is old and real: someone has to write the axioms, and someone has to keep them in sync with a changing world. The frame problem (McCarthy & Hayes, 1969) is the formal version: how do you represent what does not change without enumerating it?
Symbolic systems are also brittle at the perceptual boundary. A planner that expects a clean predicate like on(cup, table) does not know what to do with a smudged image, an occluded object, or a novel category. The symbol is only as good as the grounding beneath it.
The reliability gap
Put the two profiles together and you get the reliability gap: systems that are fluent but unfaithful, capable but ungrounded, general on the training distribution but brittle under composition. The gap is not a single bug. It is a family of failures that appear when a learned representation has to support a reasoning process that was never part of its training objective.
| Dimension | Neural | Symbolic |
|---|---|---|
| Strength | Perception, robustness, scaling from data | Composition, deduction, verification |
| Weakness | Systematic recomposition, accountability | Perception, model acquisition, open worlds |
| Typical failure | Confident answer outside the training distribution | Correct reasoning over the wrong or missing model |
| What it needs | A constraint, a memory, a check | A ground, a perception, a way to learn |
| What NeSy adds | Structure that survives recombination | Grounding that survives noise |
Neurosymbolic AI is the bet that the interface can be made explicit — that you can keep the perceptual strengths of neural networks and the compositional strengths of symbolic systems without pretending the tension disappears. The bet is not always won. A large part of this course is about when it is, and what it costs.
02 / The formulationWhat exactly is a neurosymbolic model?
There is no single canonical definition. The field is defined by a family of architectures, not by a shared formalism. But a workable formulation is useful: it makes the design choices visible, and it gives us a way to compare systems that look very different.
A neurosymbolic system has three parts: a neural component that maps raw input to a continuous representation; a symbolic component with a formal language, a semantics, and a knowledge base; and an interface that couples them, such that the symbolic component constrains, explains, or is grounded in the neural component’s representations.
Let X be the input space (images, text, states), Y the output space (answers, plans, actions, proofs), and K a knowledge base in a formal language L. A neural encoder parameterized by θ defines a representation Z, either deterministically, z = fθ(x), or as a distribution, pθ(z | x). A symbolic reasoner RK operates over L and K. The interface decides how Z and L meet.
Three canonical forms cover most of the literature. The first is constrained prediction: the neural model scores outputs, and the symbolic component removes the ones that violate the knowledge base.
The second is a latent symbolic variable: the neural component proposes a distribution over symbolic structures, and the symbolic component reasons over them. This is the form used by probabilistic logic programming systems such as DeepProbLog, where neural predicates produce probabilities over facts and the logic program defines the joint distribution.
The third is regularized learning: the symbolic component becomes a penalty on the neural model, so that the model is trained to satisfy the constraints rather than to have them imposed after the fact. Logic Tensor Networks and semantic loss are the canonical examples.
These three forms already suggest a taxonomy of interfaces. The course uses five, because they correspond to five genuinely different engineering choices — and because most real systems combine them.
| Interface | What it does | Canonical systems | What it buys | What it costs |
|---|---|---|---|---|
| Logic as loss | Compiles constraints into a differentiable penalty | Semantic loss, LTN, DL2 | End-to-end training; soft constraints | Hard constraints become soft; independence assumptions |
| Logic as architecture | Puts a symbolic executor inside the computation graph | DeepProbLog, NeurASP, DeepStochLog, Scallop, ULLER | Exact semantics; compositional structure | Inference cost; gradient quality |
| Logic as data | Uses symbols to structure inputs, outputs, or embeddings | Knowledge-graph and ontology embeddings, rule mining | Interpretable structure; knowledge transfer | Embedding distortion; schema drift |
| Logic as search | Neural proposals plus symbolic search or verification | ILP, program synthesis, AlphaGeometry, Lean | Compositional generalization; proofs | Search cost; proposal quality |
| Logic as verifier | Neural action plus symbolic monitor, shield, or repair | Runtime monitoring, STL, conformal bounds | Safety; accountability | Model fidelity; monitor coverage |
The categories are pedagogical, not exhaustive. A system can use a logic loss and a verifier; a probabilistic logic program is both an architecture and a semantics; a theorem prover can be used as a search procedure and as a verifier. The point is not to sort every paper into one box. The point is to ask, for any system: where is the interface, and what does it guarantee?
Garcez and Lamb describe neurosymbolic AI as the “third wave” of AI, integrating learning and reasoning rather than choosing one (Artificial Intelligence Review, 2023, DOI 10.1007/s10462-023-10448-w). Kautz’s taxonomy (NeSy Summer School 2024) and the NeSy conference series use different cuts. This lecture’s five-interface scheme is a teaching device, not a claim of consensus.
03 / The mapWhere neurosymbolic models sit among AI models.
“Neurosymbolic” is not a point on a list; it is a region of design space. Four axes are enough to locate most systems, and to see why two papers that both call themselves neurosymbolic can have almost nothing in common.
- Representation. From fully symbolic (logic, rules, programs) to fully neural (vectors, attention, policies).
- Inference. Deduction (what follows from what), induction (what generalizes from examples), abduction (what would explain the observation).
- Coupling. Pipeline (one component feeds the next), nested (one inside the other), joint (trained together), tool-use (one calls the other).
- Guarantee. Empirical (tested on a benchmark) or formal (a proof, a soundness result, a certificate).
The map explains a confusing fact about the field: two systems can share the label neurosymbolic and share almost no machinery. An expert system and a vision-language-action policy sit at opposite corners. A probabilistic logic program and a theorem prover both use logic, but one is a learning architecture and the other is a search procedure. The label is a region, not a family tree.
| System | Neural part | Symbolic part | Interface | Inference | Guarantee |
|---|---|---|---|---|---|
| Expert system | None | Rules and facts | Pipeline | Deduction | Rule-level, not world-level |
| Bayesian network | None | Graphical model | Joint | Probabilistic deduction | Empirical |
| ILP | Weak or none | Logic programs | Search | Induction | Empirical |
| DeepProbLog | Neural predicates | Probabilistic logic | Architecture | Probabilistic deduction | Empirical |
| NS-CL | Object perception | Programs | Architecture | Deduction | Empirical |
| AlphaGeometry | Language model | Deduction engine | Search | Deduction | Formal proof |
| VLA policy | Policy network | None | None | Reactive | None |
Give a tuple, not a label: (representation, inference, coupling, guarantee). “A neural perception module coupled to a probabilistic logic program by a differentiable executor, supporting probabilistic deduction with empirical guarantees” is more informative than “neurosymbolic.” The tuple is also a design checklist: if you cannot fill a slot, the system probably has not made that choice yet.
04 / History & philosophyThe arguments are older than the models.
The current debate about symbols and vectors is a rerun of a much older argument about what thought is. The models are new; the fault lines are not. A short history is useful because it explains why the field keeps returning to the same questions — meaning, grounding, composition, and the limits of formal systems.
A short timeline
Aristotle, Prior Analytics
Syllogistic logic: the first formal account of valid inference. The idea that reasoning has a syntax is born.
Leibniz, calculus ratiocinator
A universal calculus for reasoning, unpublished in his lifetime. The dream of a machine that settles disputes by calculation.
Frege, Begriffsschrift
Predicate logic with quantifiers. The logicist program: mathematics as logic. The representational language of symbolic AI is now in place.
Gödel, incompleteness
Any sufficiently expressive formal system has true statements it cannot prove. The limits of formalism become a philosophical problem, not just a technical one.
Turing, computability
The universal machine and the limits of mechanical procedure. Computation becomes a formal object — and a bridge between logic and machines.
McCulloch & Pitts
A logical calculus of neural activity. Neurons as threshold units; the first mathematical bridge between logic and networks.
Dartmouth; Logic Theorist
Newell and Simon’s program proves theorems from Principia Mathematica. Symbolic AI becomes a research program with a demo.
McCarthy: LISP and common sense
LISP gives symbolic AI its language; “Programs with Common Sense” gives it its ambition — and its first hard problem, the representation of everyday knowledge.
Two critiques
Minsky and Papert’s Perceptrons exposes the limits of single-layer networks; McCarthy and Hayes’s frame problem exposes the limits of naive logical representation. Both critiques shape the next two decades.
Expert systems, then winter
MYCIN, DENDRAL, and Cyc show that rules can encode expertise — and that maintaining them is expensive. The first AI boom is followed by the first winter.
Backpropagation; probabilistic reasoning
The PDP volumes and backpropagation revive connectionism. Pearl’s Probabilistic Reasoning in Intelligent Systems formalizes uncertainty. Learning and probability re-enter the picture.
Harnad, the symbol grounding problem
How does a symbol acquire meaning from the world? The question that neural perception makes urgent — and that NeSy inherits.
AlexNet; transformers
Scale, data, and attention change what neural systems can do. The bitter lesson looks less like a slogan and more like an empirical trend.
The third wave — and its critics
Sutton’s “Bitter Lesson” argues that scale and learning tend to win. Garcez and Lamb’s “third wave” argues for integration. AlphaGeometry shows a neural model and a deduction engine can produce formal proofs. LLMs with tools make the interface a product category.
The two philosophical camps
Symbolic AI inherits the rationalist tradition: thought is structured, and structure can be written down. Newell and Simon’s Physical Symbol System Hypothesis (1976) made this explicit: a physical symbol system has the necessary and sufficient means for general intelligent action. Logic is the language; search is the procedure; knowledge is the bottleneck.
Connectionism inherits the empiricist tradition: thought is what a network learns from experience. Knowledge is distributed across weights, not stored in propositions. The strength is robustness and perception; the weakness is that the learned structure is not directly inspectable, and does not reliably compose.
The philosophical arguments sharpen the technical ones:
- The symbol grounding problem (Harnad, 1990): a symbol is arbitrary unless it is connected to perception and action. A dictionary defines words in terms of other words; something has to touch the world.
- The Chinese Room (Searle, 1980): manipulating symbols according to rules is not the same as understanding them. Syntax is not semantics.
- The frame problem (McCarthy & Hayes, 1969): a formal model must represent what changes and, implicitly, what does not. The “does not” is enormous.
- Abduction (Peirce): most of what we call explanation is inference to the best explanation, not deduction from premises. A system that only deduces cannot diagnose.
- Embodiment (Dreyfus, 1972): intelligence is situated in a body and a world, not in a disembodied symbol system. The critique is old, but it anticipates the robotics problems of today.
Neurosymbolic AI is often presented as a synthesis of the two camps. The honest version is narrower: it is a set of engineering strategies for making the interface explicit, motivated by the observation that neither camp alone delivers composition, grounding, and accountability at once. The synthesis is a research program, not a settled philosophy.
Sutton’s “Bitter Lesson” (2019) argues that the biggest gains in AI have come from methods that scale with compute and learn from data, not from methods that encode human knowledge. If that trend continues, neurosymbolic complexity has to earn its place. The strongest justifications are not “symbols are more interpretable” in the abstract, but concrete: less data, better composition, formal guarantees, or a capability that scale alone does not deliver. Keep that bar in mind for every system in this course.
05 / The problemsWhat NeSy claims to solve — and what it does not.
The field’s claims are easier to evaluate if they are separated by problem. The table below lists the eight claims that recur most often, the mechanism that is supposed to deliver them, the evidence, and the caveat. The evidence is uneven: some claims are demonstrated on synthetic benchmarks, some on real tasks, some only in theory.
| Problem | Why pure neural struggles | NeSy mechanism | Evidence | Caveat |
|---|---|---|---|---|
| Data efficiency | Needs many examples to learn a rule that could be stated once | Background knowledge constrains the hypothesis space | LTN, DeepProbLog, semantic loss | Knowledge can be wrong or incomplete; constraints can hurt if mis-specified |
| Compositional generalization | Recombines only what it has seen in similar combinations | Symbolic composition of learned concepts | NS-CL, CLEVR; program synthesis | Synthetic benchmarks; open-world composition is harder |
| Long-horizon reasoning | Errors compound; no explicit state | Plans and state transitions; search over symbols | LLM+P, SayCan, LLM-Modulo | Requires a model of the environment; grounding errors dominate |
| Interpretability | Distributed representations; post-hoc explanations | Symbolic intermediates that can be inspected | NS-VQA, Logic-LM, program traces | An interpretable intermediate can still be wrong |
| Verification and safety | No formal guarantee about behavior | Constraints, monitors, shields, proofs | Shielding, STL, conformal bounds, AlphaGeometry proofs | The guarantee is only as good as the model and the specification |
| Knowledge integration | Knowledge is implicit in weights; hard to update | Ontologies, rules, knowledge graphs | KG reasoning; ontology embeddings | Schema drift; knowledge conflicts; maintenance cost |
| Grounding | Symbols are not connected to perception | Perception-to-symbol interfaces; scene graphs | NS-CL, NS-VQA, ConceptGraphs | Perception errors propagate; symbols lose nuance |
| Discovery | Generates plausible patterns, not checked hypotheses | Search over hypotheses with a verifier | AlphaGeometry; program synthesis; ILP | Verification is domain-specific; search can be expensive |
Two cautions. First, the table is a map of claims, not a scorecard. A system that helps with data efficiency may hurt on open-world robustness. Second, the evidence is often narrower than the claim. CLEVR is synthetic. AlphaGeometry is geometry. Shielding is only as good as the specification. The course will keep asking: on what benchmark, under what assumptions, with what guarantee?
It does not solve open-world perception, common sense, causal discovery, or the scaling laws of learning. It does not make a bad knowledge base good. It does not replace evaluation. It is a set of interface strategies, not a general theory of intelligence.
The rest of this lecture makes the claims concrete. Seven worked examples, one per application family, each with the same anatomy: a neural part, a symbolic part, an interface, and a guarantee.
06 / Seven examplesOne anatomy, seven domains.
The fastest way to understand neurosymbolic AI is to read a set of systems along the same anatomy. Each example below has a neural part, a symbolic part, an interface, and a claim. The domains are deliberately different: vision, probabilistic logic, constraint satisfaction, mathematics, robotics, language, and knowledge graphs. The pattern is what repeats.
NS-CL on CLEVR
A neural scene parser learns object attributes; a symbolic program composes them. The program is the explanation.
DeepProbLog on MNIST-Add
A digit classifier supplies probabilities to a logic program. The program defines the sum exactly; the network learns the digits end-to-end.
Sudoku: rules repair perception
A noisy digit classifier proposes; the row, column, and box constraints dispose. The rules can correct a misread digit and supervise the classifier.
AlphaGeometry
A language model proposes auxiliary constructions; a symbolic deduction engine checks and completes the proof. The output is a certificate, not a plausible sentence.
SayCan
An LLM scores candidate skills; learned value functions say which ones the robot can actually do. Language supplies the plan; affordances supply the grounding.
Logic-LM
An LLM translates a problem into a symbolic formulation; a solver does the inference; solver errors are fed back to repair the translation.
Knowledge-graph reasoning
Embeddings supply similarity; rules and constraints supply structure. The combination is a prior over what a missing link could be — and a trace of why.
Sudoku is the smallest complete neurosymbolic story. A classifier looks at a handwritten grid and produces a probability for each digit. The rules say: every row, every column, every box contains each digit exactly once. The rules can overrule the classifier, and the classifier can be trained against the rules. The interactive lab lets you turn the perception noise up and watch the logic repair the grid — or fail when the clues are genuinely ambiguous.
Read the gallery as a matrix
The same anatomy recurs across domains. The differences are in the interface and the guarantee, not in the slogan.
| Example | Neural part | Symbolic part | Interface | Inference | Guarantee |
|---|---|---|---|---|---|
| NS-CL | Object perception | Programs | Architecture | Deduction | Empirical |
| DeepProbLog | Digit classifier | Probabilistic logic | Architecture | Probabilistic deduction | Empirical |
| Sudoku | Digit probabilities | ASP/ProbLog constraints | Architecture | Constraint satisfaction | Empirical |
| AlphaGeometry | Language model | Deduction engine | Search | Deduction | Formal proof |
| SayCan | LLM + value functions | Skill affordances | Search | Planning | Empirical |
| Logic-LM | LLM formalizer | Solver | Tool use | Deduction | Empirical / formal |
| KG reasoning | Embeddings | Rules and constraints | Data | Deduction / induction | Empirical |
Notice what the table makes visible. The strongest guarantees appear where the symbolic part can check the neural part (AlphaGeometry). The weakest guarantees appear where the symbolic part is only a constraint on a learned representation (KG embeddings). The middle cases — NS-CL, DeepProbLog, Sudoku — are the most instructive, because they show what a well-designed interface can buy without a full proof.
07 / The course mapHow the rest of the course fits.
The 21-lecture arc follows the spine of this lecture: framing, the two worlds, the five interfaces, the three inferences, applications, and frontiers. Lecture 01 is the map; Lectures 02–05 build the two parent paradigms and the bridge; Lectures 06–11 take the five interfaces one at a time; Lectures 12–15 turn to deduction, induction, and abduction with language models; Lectures 16–20 apply the whole thing across domains; Lecture 21 is evaluation and the frontier.
If you want foundations, read 01 → 05. If you want methods, read 06 → 11. If you want applications, read 16 → 20. If you want the frontier, read 21 after 01 and 06. The order is a suggestion; the map is not a syllabus with locks.
How to read a neurosymbolic paper
Five questions will get you most of the way through any paper in this field. Ask them in order; the answers are the paper’s real contribution, even when the abstract is about a benchmark.
- What is the neural component? A classifier, an encoder, a language model, a policy, a value function. What does it map from and to?
- What is the symbolic component? A logic program, a set of constraints, a planner, a theorem prover, a graph. What language does it use, and what does it assume?
- What is the interface? Loss, architecture, data, search, or verifier. Where does information cross, and in which direction?
- What is the guarantee? Empirical, formal, or none. If formal, what exactly is proved — soundness, completeness, robustness, safety?
- What does the benchmark actually test? Composition, grounding, data efficiency, long-horizon planning, or something else. A benchmark can be diagnostic without being realistic.
If the paper cannot answer question 3, it is probably a pipeline, not a neurosymbolic system in the strong sense. If it cannot answer question 4, its claim is empirical, whatever the abstract says. If it cannot answer question 5, the result may be real but the lesson may be narrow.
08 / RecapWhat you should be able to do now.
Define a neurosymbolic system as a neural component, a symbolic component, and an explicit interface.
Name the five interfaces: loss, architecture, data, search, verifier.
Place a system on the map using the tuple (representation, inference, coupling, guarantee).
Explain why pure neural and pure symbolic systems fail in different ways.
Trace the history from syllogisms to expert systems to deep learning to the third wave.
Separate the eight NeSy claims and state the caveat for each.
Read a worked example along the anatomy: neural, symbolic, interface, guarantee.
Ask the five questions that expose what a NeSy paper actually contributes.
Exercises
- Define it yourself. Write a one-paragraph definition of neurosymbolic AI that does not use the words “combine,” “integrate,” or “hybrid.” Then compare it with the definition in §2.
- Classify seven systems. Take the seven examples in §6 and fill the tuple (representation, inference, coupling, guarantee) for each. Where are you unsure? What would you need to read to decide?
- Find the interface. Pick a paper from the reading list. Identify the exact line of code or equation where the neural and symbolic components exchange information. If you cannot find it, say so — that is a finding.
- Break the Sudoku demo. In the lab, increase the perception noise until the solver produces a wrong solution or no solution. What fails first: the perception, the constraints, or the assumption that the clues are correct?
- Argue the bitter lesson. Write the strongest case that neurosymbolic AI is unnecessary at scale. Then write the strongest case that it is necessary. Which evidence would change your mind?
- Design a toy system. Choose a small domain (a board game, a scheduling problem, a household task). Specify the neural part, the symbolic part, the interface, and the guarantee. Do not implement it yet.
Check your understanding
Ten questions, with explanations. The score is not the point; the questions you cannot answer are the reading list.
Reading list
The first five are the spine of this lecture. The rest are the next layer.
The Neuro-Symbolic Concept Learner
Mao et al. · ICLR 2019 · the hook, in full
DeepProbLog: Neural Probabilistic Logic Programming
Manhaeve et al. · NeurIPS 2018 · the architecture interface
NeurASP: Embracing Neural Networks into Answer Set Programming
Yang, Ishay & Lee · IJCAI 2020 · the Sudoku example
Solving olympiad geometry without human demonstrations
Trinh et al. · Nature 2024 · the search interface, with proofs
Do As I Can, Not As I Say
Ahn et al. · 2022 · language grounded in affordances
Logic-LM
Pan et al. · EMNLP Findings 2023 · translate, solve, repair
Neurosymbolic AI for Reasoning over Knowledge Graphs: A Survey
Survey · 2023 · the data interface
Faith and Fate: Limits of Transformers on Compositionality
Dziri et al. · NeurIPS 2023 · the neural failure mode
LLMs Can’t Plan, But Can Help Planning in LLM-Modulo Frameworks
Kambhampati et al. · ICML 2024 · the verifier interface
Neurosymbolic AI: the 3rd wave
Garcez & Lamb · Artificial Intelligence Review 2023 · the framing
Figures 0.1, 3.1, and the gallery diagrams are schematic redrawings, not reproductions. The citations identify the systems and the claims; the drawings are ours. If a figure is ever reproduced from a paper, it will carry the license and the exact source.